Lab
My local AI lab
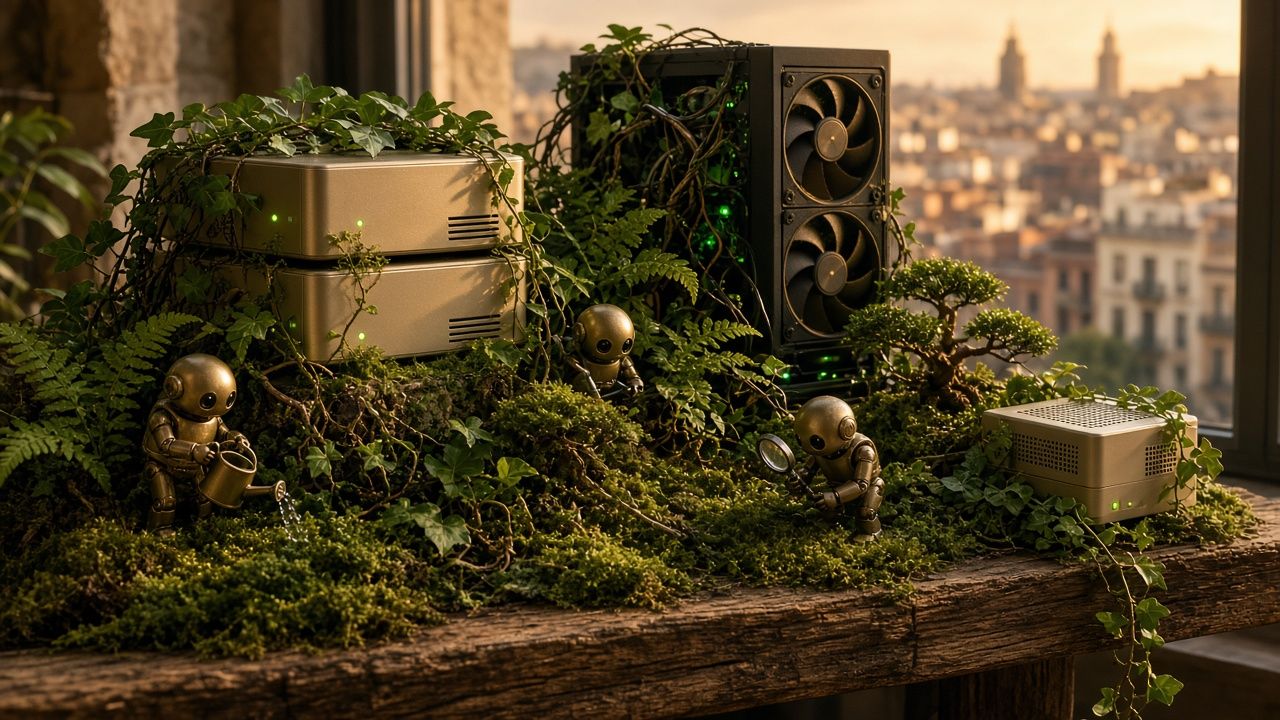
Two desktop supercomputers, three graphics cards, a mini PC and lots of agents. This is the system I work with every day.
- of unified memory in the cluster
- 256 GB
- of VRAM across three RTX GPUs
- 56 GB
- between the two nodes
- 200 Gb/s
- tokens served (May–Sep 2026)
- ≈4.7 B
The idea
I wanted to test something simple: whether one person, alone at home, can have an AI as useful as the big platforms without sending them a single piece of data. The answer is yes, as long as it’s set up properly and kept alive while models change every week.
What started as an experiment now supports my daily work, my family’s, some friends’ and client projects. Everything I offer at file.cat has been tested here first.
The hardware
| Component | What it is | What I use it for |
|---|---|---|
| 2 × NVIDIA DGX Spark (ASUS Ascent GX10) | GB10 superchip with 128 GB of unified memory each, linked by ConnectX-7 at 200 Gb/s | Running the large reasoning model in tandem (tensor parallel), with up to a million tokens of context |
| Server with 3 GPUs | One 24 GB RTX 3090 and two 16 GB RTX 4060 Ti | Coding, vision, embedding, reranker, voice, transcription and image models |
| Mini PC with Proxmox | Ryzen and 16 GB, with three LXC containers | The model gateway, the agents and the dashboards, so the inference nodes only do inference |
| The farm’s Proxmox | Home Assistant, cameras and the virtualized GPU server | The agricultural and household side |
| Network | Tailscale, automatic TLS with Caddy and dynamic DNS | Secure access from anywhere without opening unnecessary ports |
The models
I don’t mention specific names on the commercial site because they change every few weeks, but here I do:
| Role | Current model | Where it runs |
|---|---|---|
General reasoning (spark) |
Qwen3.8-Flash-Next (~180B MoE, NVFP4), native vision, 512K context | Two-Spark cluster |
Fast code (coder) |
Qwen3.8 27B with DFlash2, ~200 tok/s | RTX 3090 |
Light code (coder2) |
Qwen3.8 9B | RTX 4060 Ti |
Crop pests (agripests) |
Gemma 4 fine-tuned for agricultural vision | RTX 4060 Ti |
| Embeddings and reranker | Qwen3-Embedding-4B and Qwen3-Reranker-4B | RTX 4060 Ti |
| Voice and transcription | Qwen3-TTS with my cloned voice, and Whisper | RTX 4060 Ti |
| Image and video | Qwen-Image 2.1 and ComfyUI models | RTX 3090 |
The cluster has also run DeepSeek V4 Flash with a million tokens of context, the 320-billion-parameter GLM-5.3-Flash and Qwen3.5-122B. Swapping the big model without interrupting service is part of the job: I made three swaps in five days in August while the agents kept working.
The gateway: my private “OpenAI”
Everything goes through a LiteLLM gateway with eight stable roles. Clients ask for spark or coder, not a specific model, so I can change what’s behind them without anyone touching their configuration.
- Accounts per person and per agent, teams and budgets.
- OpenAI-compatible endpoint, published with TLS at
openai.file.cat. - Control over each model’s reasoning mode in the alias itself.
- My own usage dashboard that breaks tokens down by person and by model.
Between May and October 2026 it served about 11.15 billion tokens. A single user, with their own agent, already tops 6 billion.
GPU arbiters
An RTX 3090 can’t hold a 27B coding model and image generation at the same time. Instead of choosing, I wrote two GPU arbiters that switch turns automatically: if a request comes in for the model that’s switched off, the arbiter brings it up, waits until it’s ready and responds. If the card is busy with a render, it replies with a clear message and an estimated wait time.
What runs on top
- Nine agent profiles on a single Discord gateway, each with its own vector memory. They’re explained in Agents.
- Isolated instances for the family farm, for my sisters and for the Nuzic team.
- Voice: meeting transcription that identifies who’s speaking, and spoken replies in my voice.
- Images: local generation with Qwen-Image, straight from the agents.
- Search and documents: SearXNG, Firecrawl and PDF extraction, all self-hosted.
- Dashboards and alerts: a status and usage dashboard built by the agents, and a watchdog that sends an alert on Discord if something goes down.
Numbers I’ve measured
| Test | Result |
|---|---|
| Qwen3.8-Flash-Next, 8 conversations at once | ~325 tok/s aggregate |
| Same model, 1 conversation | 57 tok/s on prose and 72 tok/s on code |
| 27B coding model on an RTX 3090 | ~200–222 tok/s |
| Copying 135 GB of weights between nodes | ~3 minutes |
| Fallback with the local model down | 0.6 s |
What I’ve learned
- Memory rules. With unified memory, every point of reserved memory counts, and long context doesn’t come free.
- Inference nodes should only do inference. Moving the gateway and agents to a mini PC stabilized everything.
- Never a hidden fallback. If the local model fails, it shows; nobody switches models without knowing it.
- Stable roles, swappable models. The client asks for a role; what’s behind it can get better every week.
- Measure everything. Speed, memory, consumption and who uses what. Without numbers, there are no decisions.
Want one like this?
I build custom versions for businesses, from a single-GPU workstation to a cluster like this one. I explain it at file.cat, with ballpark prices.